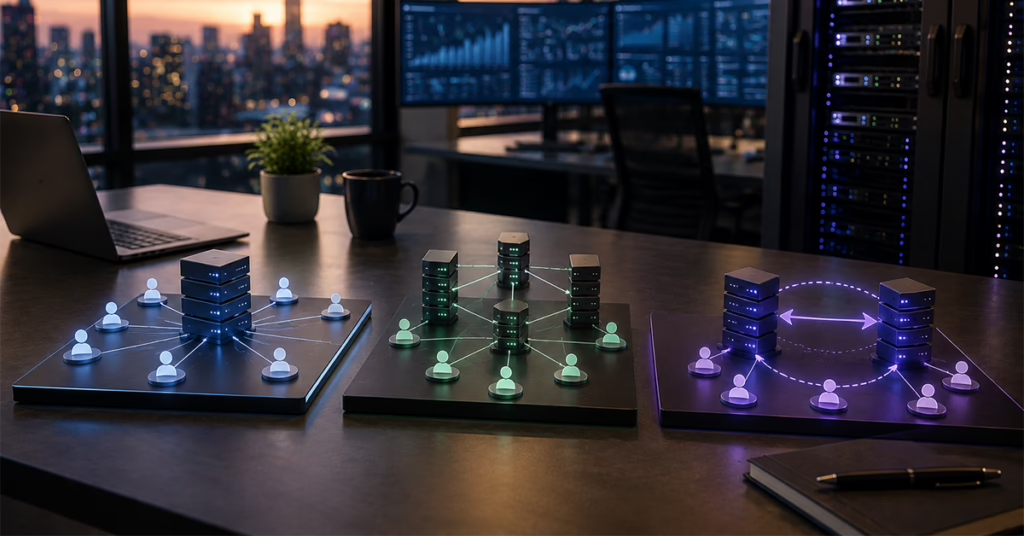
AAA server rollout strategies fall into three models, big-bang (fast, higher risk), phased by subscriber segment (slower, lower risk), and parallel-run (old and new authentication, authorization, and accounting platforms live simultaneously, lowest risk) chosen based on operator scale, network complexity, and risk tolerance. Most large operators combine models, sequencing them differently per network type.
Most guidance on AAA deployments answers the question how do I execute the rollout? This article answers the one that comes before it: which rollout model should I execute in the first place? That is a real strategic choice, not a formality. A big-bang cutover on a converged national network and a six-month parallel run for a single-access-type regional internet service provider (ISP) are both, in the wrong context, expensive mistakes: the first in outage risk, the second in duplicated infrastructure nobody needed.
The choice comes down to three variables: how many subscribers are affected if the rollout goes wrong (blast radius), how many network types the AAA serves (complexity), and how much appetite the business has for risk versus cost. This article compares the three rollout models against those variables, adds the cross-cutting question of network-type sequencing, and closes with a decision table matching operator profiles to strategies.
Big-Bang Rollout: When It Makes Sense
A big-bang rollout replaces the legacy AAA with the new platform in a single cutover event: all subscribers, all network types, one change window. It is the fastest and cheapest model, with one migration project and no prolonged dual-platform operation. It is also the highest-risk one, because the blast radius of any fault is the entire subscriber base at once.
The model has a legitimate home. Consider a smaller operator with one access type: a regional fixed-broadband ISP whose AAA terminates RADIUS for a single Broadband Remote Access Server or Broadband Network Gateway (BRAS/BNG) estate. Its failure domain is small enough that a well-rehearsed cutover, executed in a low-traffic window with a tested rollback plan, is often the rational choice. The characteristics that qualify a network for big-bang are a single protocol footprint, a manageable NAS (network access server) inventory, and a rollback that has actually been rehearsed rather than merely written down.
Two things disqualify a network. One is breadth: once the AAA carries multiple network types, the single change window stops being a simplification. The other is scale. On a large enough subscriber base, mass re-authentication after a failed cutover arrives as one simultaneous wave rather than spread across a normal day’s login curve, and it reads as a national outage in every dashboard that matters. At that point a single window is not simplicity, it is concentrated risk. The common mistake is choosing big-bang because it is the shortest project plan, not because the network’s risk profile supports it.
Phased Rollout by Subscriber Segment
A phased AAA server rollout migrates subscribers in planned waves (by region, realm, NAS group, or service tier), with each wave validated before the next begins. Risk drops because any fault is contained to one wave, not the whole base; the price is a longer timeline and a transition period in which both platforms run and both must be operated.
Wave design is where this model is won or lost. Good waves are independently verifiable: a region or NAS group whose authentication success rate, session behavior, and accounting records can be reconciled on their own before the next wave moves. Many operators start with a deliberately low-stakes wave (a small region, a staff-and-friendly-user realm) to prove the runbook, then widen the waves as confidence and measured evidence accumulate.
The phased model fits large and complex operators almost by default, because it is the only model that lets a multi-million-subscriber migration fail small. Its real cost is discipline rather than money: each wave needs entry and exit criteria, a reconciliation step, and an owner, or the “phases” collapse into an unplanned big-bang spread over more weekends. The wave mechanics themselves inventory, per-device secrets, and per-wave reconciliation sit downstream of this decision.
Parallel-Run Migration
A parallel-run AAA server migration keeps the legacy and new platforms live simultaneously, with the new system shadowing real production traffic (receiving the same requests, producing its own responses and accounting records) before it owns any of it. Traffic then shifts once the new platform’s behavior has been reconciled against the legacy system’s on live load. Of the three models it carries the least risk and the highest cost, because two full AAA estates run for the duration.
Safety here is not a slogan; it is measurable. Shadowing real traffic surfaces the faults that staging never does: the undocumented vendor-specific attribute, the NAS with a nonstandard retry pattern, the accounting mismatch that only appears at production volume. And it surfaces them while the legacy platform still holds service. Rollback is not an emergency procedure but the default state: the old system never stopped running.
Parallel-run earns its cost where the downside of failure is severest: Tier-1 subscriber bases, strict regulatory or service-level agreement (SLA) exposure, or migrations off a legacy AAA whose behavior is poorly documented and must be learned by observation. It also pairs naturally with the phased model: run the platforms in parallel within each wave, and shift traffic wave by wave.
The new platform’s architecture decides whether any of this is practical. Alepo AAA Server runs N+1 and N+N redundancy with real-time database replication, engineered for 99.999% availability, so both estates can stay live through a long transition without the new one becoming its own single point of failure. It deploys in containers (Docker and Kubernetes), on virtual machines, on bare metal, in private cloud, or on-premises, which matters here, because a parallel run needs a platform you can stand up alongside the incumbent without rebuilding your operating model. Whatever platform you deploy, insist on a measured throughput number of your own, recorded under your own peak authentication and accounting profile rather than taken from a datasheet ceiling.
Sequencing by Network Type: Broadband, Mobile, Wi-Fi
A converged operator should sequence its AAA rollout by network type rather than migrate every type at once. One AAA may terminate RADIUS for fixed broadband, Diameter (SWx, S6b, SWm) for mobile data, and the Extensible Authentication Protocol (EAP) family (EAP-SIM, EAP-AKA, EAP-AKA’) for carrier Wi-Fi and Wi-Fi offload. Those segments differ in protocol complexity, session behavior, and failure visibility. They should not automatically share one rollout wave, or even one rollout model.
A common sequencing pattern runs simplest-first: fixed broadband ahead of Wi-Fi, mobile last. Broadband RADIUS is typically the most self-contained segment, with well-understood attributes and a known BRAS/BNG inventory, and it makes a controlled proving ground. Wi-Fi introduces EAP method coverage and device diversity. Mobile lands last because Diameter integration touches the most adjacent systems, Home Subscriber Server (HSS) lookups over SWx, packet-core session flows so it benefits most from a platform already proven on live traffic in the other segments.
Networks that also run TACACS+ for device administration can usually move that footprint independently, since it serves administrators rather than subscribers. The strategic point is that segments can, and often should, use different models: big-bang for a small, clean broadband estate; parallel-run for the mobile segment where integration risk concentrates. Treat “which strategy?” as a per-segment decision made under one program, with one sequencing logic, not a single answer imposed network-wide.
Matching AAA Server Rollout Strategies to Operator Profile
There is no universally correct AAA server rollout strategy, only a correct match between model and operator profile. Three variables do most of the deciding: subscriber scale (the blast radius of a fault), network complexity (how many access types and protocol paths the AAA carries), and risk tolerance.
Table: AAA server rollout strategies compared, how each model works, its risk profile, and the operator profile it fits.
| Strategy | How it works | Risk profile | Best fit |
| Big-bang | Single cutover event; all subscribers and network types move at once | Highest: blast radius is the full subscriber base; speed and cost are the payoff | Smaller operators and mobile virtual network operators (MVNOs) with one access type, a clean NAS inventory, and a rehearsed rollback |
| Phased by segment | Migration in validated waves by region, realm, NAS group, or service tier | Moderate: faults are contained to one wave; timeline and operational discipline are the cost | Large or multi-region operators; any network too big to fail all at once |
| Parallel-run | Legacy and new platforms live simultaneously; new system shadows real traffic until reconciled, then takes ownership | Lowest: rollback is the default state; duplicate infrastructure for the duration is the cost | Tier-1 scale, strict SLA or regulatory exposure, or poorly documented legacy AAA behavior |
Read the table as a starting bias, then adjust for what it compresses. An MVNO at modest scale can often move faster than its host mobile network operator (MNO) could, because its whole-network exposure is smaller and its inventory simpler. A mid-size converged operator frequently lands on a hybrid: phased waves overall, parallel-run inside the waves that carry mobile Diameter traffic. An operator whose legacy AAA is at end of support has a timeline variable the table does not show, which narrows the choice to whichever model can be executed well in the time remaining. And an operator without the internal capacity to run two AAA estates through a long transition has a fourth variable to weigh, whether the vendor operates the platform during the migration.
Choosing Your Rollout Strategy
Three questions decide an AAA server rollout strategy: how many subscribers a fault would affect, which protocols and integrations move, and what an outage costs relative to duplicated infrastructure. The deciding sequence is short. Establish blast radius: how many subscribers, on which network types, are affected by a fault. Establish complexity: which protocols, integrations, and NAS estates move. Establish tolerance: what failure costs, and what duplicated infrastructure costs. The strategy usually falls out of those three answers. Where it does not, the tie-breaker is that outage risk tends to be remembered longer than project cost.
Two practical notes belong in any AAA server rollout plan a telecom operator writes. First, the strategy decision is upstream of, not a substitute for, execution discipline: whichever model you choose still requires the staging validation, capacity testing, and rollback rehearsal that protect a cutover. RADIUS behavior defined in RFC 2865 is a standing argument for testing every protocol path before it carries production traffic, a shared-secret mismatch typically produces no response at all rather than a clear rejection, because the server silently discards a request it cannot validate. Second, the platform you are rolling out constrains the strategies available to you: a phased or parallel-run model requires an AAA Server that supports redundant operation with real-time database replication, and that can take traffic in stages rather than only at cutover.
Deciding between these models for your own network? Walk your operator profile (scale, segments, risk posture) against the Alepo AAA Server in a working session, including which redundancy and traffic-shifting options each rollout model actually requires.
Frequently Asked Questions
Q1. What rollout strategies exist for AAA server deployment?
Three models cover the field: big-bang (one cutover event for the whole network), phased by subscriber segment (migration in validated waves by region, realm, or NAS group), and parallel-run (legacy and new platforms live simultaneously until the new one is proven on real traffic). Large operators often combine them: phased waves with a parallel run inside each wave.
Q2. Is a phased or big-bang AAA rollout better?
Neither is better in the abstract; the decision follows risk tolerance and network complexity. Big-bang suits small, single-access-type networks with a rehearsed rollback, because the whole-network exposure is affordable. Phased suits any network too large or too entangled to fail all at once. The decision table above matches operator profile to model.
Q3. What is a parallel-run rollout strategy?
A parallel-run strategy keeps the old and new AAA platforms running simultaneously, with the new system shadowing real production traffic and its responses and accounting records reconciled against the legacy systems. Traffic shifts only once the new platform is proven, which makes rollback the default state rather than an emergency procedure, at the cost of operating two estates for the duration.
Q4. How should I sequence an AAA rollout across broadband, mobile, and Wi-Fi?
A common pattern is simplest-first: fixed broadband (self-contained RADIUS, known BRAS/BNG inventory) as the proving ground, Wi-Fi next (adds EAP method and device diversity), and mobile last, because Diameter integration with the HSS and the packet core carries the most adjacent-system risk and benefits from a platform already proven on live traffic.
Q5. Which AAA rollout strategy is lowest risk?
Parallel-run. Because the legacy platform keeps running until the new one is reconciled against it on live traffic, a fault in the new system never takes service down; the cost is running duplicate AAA infrastructure for the transition period. Phased rollout is the middle position: contained risk per wave without a full second estate for the whole program.
Q6. How do MVNOs approach AAA rollout differently than MNOs? MVNOs typically operate at smaller scale with a simpler network inventory, which shrinks the failure domain of any fault and opens up faster models, a well-rehearsed big-bang or a short, phased rollout that a host-scale MNO could not responsibly choose. The decision logic is the same; the variables just resolve differently at MVNO scale.
Q7. Can different network segments use different rollout strategies?
Yes, and for converged operators it is often the right call. Segments differ in protocol complexity and failure visibility, so a small, clean broadband estate might move big bang while the mobile Diameter segment runs in parallel until proven. Keep the segment-level choices under one program with a single sequencing logic and one owner.